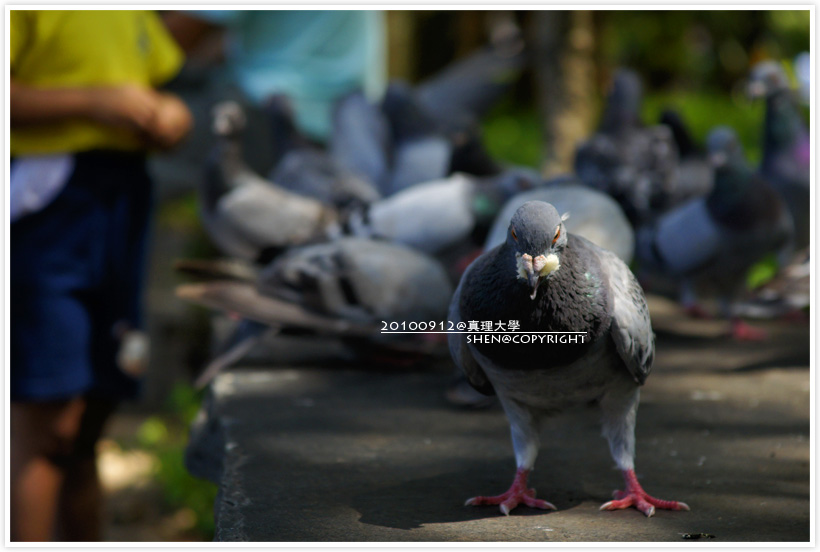
地點:真理大學內
機身:Sony A550
鏡頭:卡爾蔡斯16-80mm T* F3.5-4.5
快門:1/640s
焦距:80mm
ISO:200
這是昨天所拍攝的眾多照片中最喜愛的其中一張 ^^
 blog.Ring.idv.tw
 餵鴿子吃麵包
In Photography
地點:真理大學內
機身:Sony A550
鏡頭:卡爾蔡斯16-80mm T* F3.5-4.5
快門:1/640s
焦距:80mm
ISO:200
這是昨天所拍攝的眾多照片中最喜愛的其中一張 ^^
2010-09-14 00:09:51 | Add Comment
八里河岸(使用黑卡)In Photography
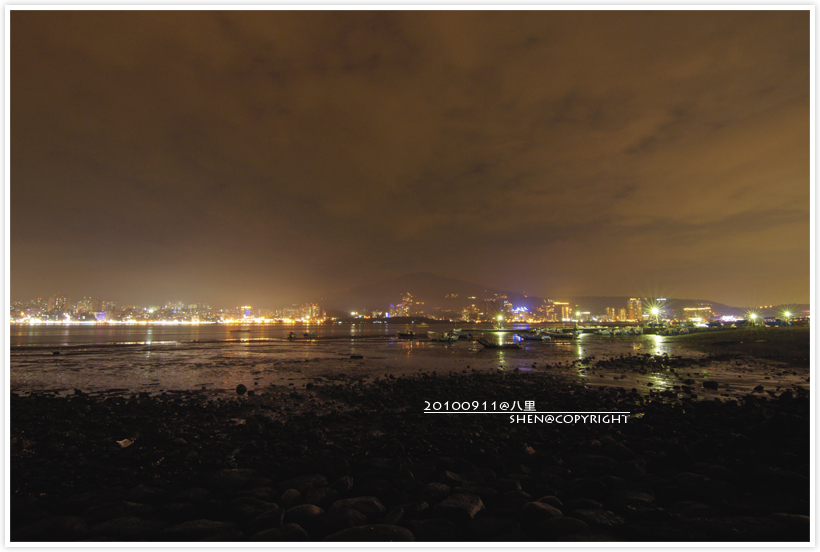
使用黑卡前 - 正常曝光25秒
使用黑卡後 - B快門曝光109秒
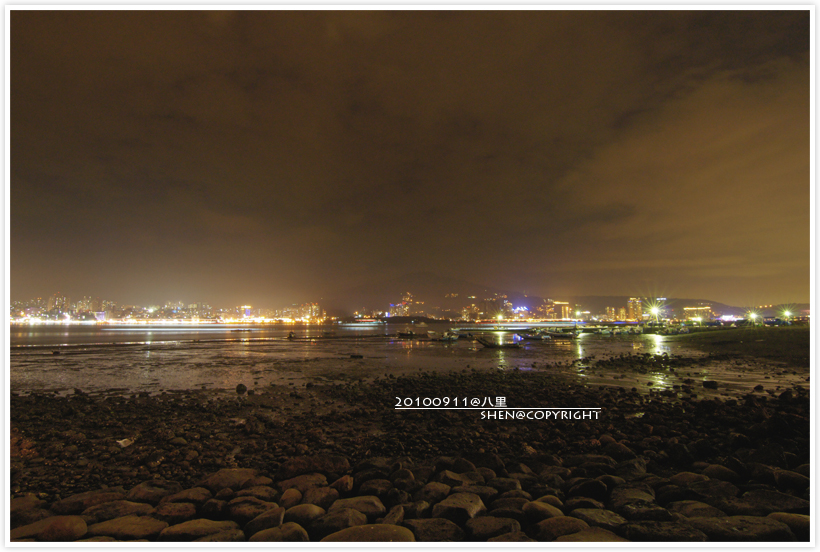
地點:八里河岸
機身:Sony A550
鏡頭:Tokina 11-16mm F2.8
焦距:11 mm
光圈:F11
ISO:200
很明顯的~ 透過使用黑卡的拍攝技巧可以取得更多的細節~ ^^
2010-09-13 23:44:04 | Comments (1)
MRUnit - 測試你的MapReduce程式In Hadoop
隨著Hadoop 0.21.0的釋出,你可以更方便的來測試你的MapReduce程式,因為它包含了一套由Cloudera所貢獻用來測試MapReudce程式的Library - MRUnit,不過目前除了官方所提供的overview.html檔之外,其它的相關文件卻相當稀少(補充中:Add MRUnit documentation),而本文純粹記錄一下簡單的WordCount測試程式(New API)來介紹MRUnit的使用方式:
TokenizerMapper
import java.io.IOException;
import java.util.StringTokenizer;

import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Mapper;

public class TokenizerMapper extends Mapper<Object, Text, Text, IntWritable>
{
	private final static IntWritable one = new IntWritable(1);
	private Text word = new Text();

	public void map(Object key, Text value, Context context) throws IOException, InterruptedException
	{
		StringTokenizer itr = new StringTokenizer(value.toString());
		while (itr.hasMoreTokens())
		{
			word.set(itr.nextToken());
			context.write(word, one);
		}
	}
}
WordCountReducer
import java.io.IOException;

import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Reducer;

public class WordCountReducer extends Reducer<Text, IntWritable, Text, IntWritable>
{
	private IntWritable result = new IntWritable();

	public void reduce(Text key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException
	{
		int sum = 0;
		for (IntWritable val : values)
		{
			sum += val.get();
		}
		result.set(sum);
		context.write(key, result);
	}
}
MRUnitTest
import junit.framework.TestCase;

import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Mapper;
import org.apache.hadoop.mapreduce.Reducer;
import org.apache.hadoop.mrunit.mapreduce.MapReduceDriver;
import org.apache.hadoop.mrunit.types.Pair;

import org.junit.Before;
import org.junit.Test;

public class MRUnitTest extends TestCase
{

	private Mapper<Object, Text, Text, IntWritable> mapper;
	private Reducer<Text, IntWritable, Text, IntWritable> reducer;
	private MapReduceDriver<Object, Text, Text, IntWritable,Text, IntWritable> driver;

	@Before
	public void setUp()
	{
		mapper = new TokenizerMapper();
		reducer = new WordCountReducer();
		driver = new MapReduceDriver<Object, Text, Text, IntWritable,Text, IntWritable>(mapper, reducer);
	}

	@Test
	public void testIdentityMapper()
	{
		Pair<Object, Text> p1 = new Pair<Object, Text>(new Object(), new Text("bar"));
		Pair<Object, Text> p2 = new Pair<Object, Text>(new Object(), new Text("foo"));
		Pair<Object, Text> p3 = new Pair<Object, Text>(new Object(), new Text("bar"));
		Pair<Object, Text> p4 = new Pair<Object, Text>(new Object(), new Text("bar"));
		driver.withInput(p1);
		driver.withInput(p2);
		driver.withInput(p3);
		driver.withInput(p4);
		driver.withOutput(new Text("bar"), new IntWritable(3));
		driver.withOutput(new Text("foo"), new IntWritable(1));
		driver.runTest();
	}
}
由於上述範例主要測試MapReduce整個流程,所以透過「MapReduceDriver」物件來驅動整個測試,當然你也可以只測試Map流程,那就透過「MapDriver」即可,另外MRUnit也支援Counters,所以也可以透過它來驗證程式。
相關資源
2010-09-13 18:01:25 | Add Comment
我把程式寫美了,但卻變慢了...昨天晚上我和同事在討論一個小程式,該程式只是需要一點小邏輯而已,並不會很複雜~ 而且可以有多種寫法,整個故事如下:
該程式需要進行一些轉換的工作,條件是將「1到12的整數,能轉換成1->12, 2->1, 3->2.... 12->11」這樣的處理,很顯然的~ 這只需要一個「if-else」判斷式即可搞定,程式如下:
if (i == 1)
	return 12;
else
	return i-1;
看起來相當直覺~ 而且可讀性也還不錯~ 只是龜毛的我硬是想要用公式來解決它,解法如下:
return (i+10)%12+1;
好了,問題來了~ 以程式碼的可讀性來說前者俱備這樣的優勢,唯一可以挑剔的就是和後者相比程式碼多了點...(其實也還好 XD)
那這兩種解法哪一種執行的效率高呢?「if-else」判斷式?還是公式?
筆者寫了個Java程式來測試~ 不過得不到答案,可能是JVM的關係導致一下子解法一快~ 一下子又解法二比較快... Orz
public class Test
{
    public static int test1(int i)
    {
        return (i + 10) % 12 + 1;
    }

    public static int test2(int i)
    {
        return (i == 1) ? 12 : i - 1;
    }

    public static void main(String[] args)
    {
        long s1 = System.nanoTime();
        for (int i = 0; i < 1000000000; i++)
            test1(i);
        long e1 = System.nanoTime();
        System.out.println(e1 - s1);

        long s2 = System.nanoTime();
        for (int i = 0; i < 1000000000; i++)
            test2(i);
        long e2 = System.nanoTime();
        System.out.println(e2 - s2);
    }
}
不過可以確定的是,如果只從被編譯後的class檔所包含的opcode來看~ 用公式解的opcode數量少了一個,但是執行測試的結果不代表用公式解的效率就比較好:
public static int test1(int);
  Code:
   Stack=2, Locals=1, Args_size=1
   0:    iload_0
   1:    bipush    10
   3:    iadd
   4:    bipush    12
   6:    irem
   7:    iconst_1
   8:    iadd
   9:    ireturn

public static int test2(int);
  Code:
   Stack=2, Locals=1, Args_size=1
    0:    iload_0
    1:    iconst_1
    2:    if_icmpne    10
    5:    bipush    12
    7:    goto    13
   10:    iload_0
   11:    iconst_1
   12:    isub
   13:    ireturn
既然如此,筆者就改用C來測試看看:
#include <stdio.h>
#include <time.h>
int test1(int i)
{
        return (i+10)%12+1;
}
int test2(int i)
{
        return (i==1)?12:i-1;
}
int main(void)
{
        clock_t start_tick, end_tick;
        double elapsed;
        start_tick = clock();
        for(int i = 0 ; i < 1000000000 ; i++)
                test1(i);

        end_tick = clock();
        elapsed = (double) (end_tick - start_tick) / CLOCKS_PER_SEC;
        printf("test1 taken:=%f\n",elapsed);

        start_tick = clock();
        for(int i = 0 ; i < 1000000000 ; i++)
                test2(i);

        end_tick = clock();
        elapsed = (double) (end_tick - start_tick) / CLOCKS_PER_SEC;
        printf("test2 taken:=%f\n",elapsed);
        return 0;
}
gcc -std=c99 -o test test.c
測試結果出爐:
test1 taken:=6.090000
test2 taken:=4.050000
「if-else」判斷式獲勝!! Orz... 那我幹嘛還花時間去想公式~ 唯一的好處就只剩下程式比較「美」罷了~ (自我感覺良好...)
最後謝謝我那位同事(匿名)陪我一起討論 ^^
2010-08-24 14:29:30 | Comments (4)
整合Cassandra和Hadoop - WordCountIn Open Source, Cassandra, Hadoop
由於Cassandra在0.6版開始提供和Hadoop整合,可以將Cassandra所儲存的資料當做Hadoop MapReduce的輸入來源,所以筆者前幾天在試著玩玩Cassandra該如何要和Hadoop整合時,用著「官方所提供的WordCount」範例,跑出來的結果居然完全錯誤!! trace了大半天才發現原來是Cassandra的Bug,還好這在最新釋出的0.6.4版已經被修正了(ColumnFamilyRecordReader returns duplicate rows),不過目前Cassandra還是沒有提供將Hadoop資料輸出到Cassandrad的介面實作(雖然可以在Reduce自行處理),這要等到0.7版才會釋出(A Hadoop Output Format That Targets Cassandra),下述就是Cassandra+Hadoop的WordCount程式:
測試資料
Key     Value
-----------------------------------------
Doc1    new home sales top forecasts
Doc2    home sales rise in july
Doc3    increase in home sales in july
Doc4    july new home sales rise
IRWordCountSetup
package cassandra;

import org.apache.cassandra.thrift.Cassandra;
import org.apache.cassandra.thrift.ColumnPath;
import org.apache.cassandra.thrift.ConsistencyLevel;
import org.apache.thrift.protocol.TBinaryProtocol;
import org.apache.thrift.protocol.TProtocol;
import org.apache.thrift.transport.TSocket;
import org.apache.thrift.transport.TTransport;

public class IRWordCountSetup
{
	public static final String UTF8 = "UTF8";

	public static void main(String[] args)throws Exception
	{
		TTransport tr = new TSocket("localhost", 9160);
		TProtocol proto = new TBinaryProtocol(tr);
		Cassandra.Client client = new Cassandra.Client(proto);
		tr.open();

		String keyspace = "Keyspace1";
		String columnFamily = "Standard1";

		ColumnPath colPathName = new ColumnPath(columnFamily);
		colPathName.setColumn("Doc".getBytes(UTF8));
		long timestamp = System.currentTimeMillis();

		client.insert(keyspace, "Doc1", colPathName, "new home sales top forecasts".getBytes(UTF8), timestamp, ConsistencyLevel.ONE);
		client.insert(keyspace, "Doc2", colPathName, "home sales rise in july".getBytes(UTF8), timestamp, ConsistencyLevel.ONE);
		client.insert(keyspace, "Doc3", colPathName, "increase in home sales in july".getBytes(UTF8), timestamp, ConsistencyLevel.ONE);
		client.insert(keyspace, "Doc4", colPathName, "july new home sales rise".getBytes(UTF8), timestamp, ConsistencyLevel.ONE);
	}
}
IRWordCount
package cassandra;

import java.io.IOException;
import java.util.Arrays;
import java.util.SortedMap;
import java.util.StringTokenizer;

import org.apache.cassandra.db.IColumn;
import org.apache.cassandra.hadoop.ColumnFamilyInputFormat;
import org.apache.cassandra.hadoop.ConfigHelper;
import org.apache.cassandra.thrift.SlicePredicate;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.FileSystem;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Job;
import org.apache.hadoop.mapreduce.Mapper;
import org.apache.hadoop.mapreduce.Reducer;
import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

public class IRWordCount
{
	static final String KEYSPACE = "Keyspace1";
	static final String COLUMN_FAMILY = "Standard1";
	private static final String CONF_COLUMN_NAME = "Doc";
	private static final String OUTPUT_PATH_PREFIX = "/tmp/doc_word_count";

	public static class TokenizerMapper extends Mapper<String, SortedMap<byte[], IColumn>, Text, IntWritable>
	{
		private final static IntWritable one = new IntWritable(1);
		private Text word = new Text();
		private String columnName;

		protected void setup(Context context) throws IOException, InterruptedException
		{
			this.columnName = context.getConfiguration().get(CONF_COLUMN_NAME);
		}
		public void map(String key, SortedMap<byte[], IColumn> columns, Context context) throws IOException, InterruptedException
		{
			IColumn column = columns.get(columnName.getBytes());
			if(column == null)
				return;

			String value = new String(column.value());
			System.out.println("read " + key + ":" + value + " from " + context.getInputSplit());

			StringTokenizer itr = new StringTokenizer(value);
			while (itr.hasMoreTokens())
			{
				word.set(itr.nextToken());
				context.write(word, one);
			}
		}
	}

	public static class IntSumReducer extends Reducer<Text, IntWritable, Text, IntWritable>
	{
		private IntWritable result = new IntWritable();

		public void reduce(Text key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException
		{
			int sum = 0;
			for (IntWritable val : values)
			{
				sum += val.get();
			}
			result.set(sum);
			context.write(key, result);
		}
	}

	public static void main(String[] args) throws Exception
	{
		Path output = new Path(OUTPUT_PATH_PREFIX);
		Configuration conf = new Configuration();

		FileSystem fs = FileSystem.get(conf);
		if(fs.exists(output))
			fs.delete(output, true);

		String columnName = "Doc";
		conf.set(CONF_COLUMN_NAME, columnName);
		Job job = new Job(conf, "wordcount");
		job.setJarByClass(IRWordCount.class);
		job.setMapperClass(TokenizerMapper.class);
		job.setCombinerClass(IntSumReducer.class);
		job.setReducerClass(IntSumReducer.class);
		job.setOutputKeyClass(Text.class);
		job.setOutputValueClass(IntWritable.class);

		job.setInputFormatClass(ColumnFamilyInputFormat.class);
		FileOutputFormat.setOutputPath(job, output);

		ConfigHelper.setColumnFamily(job.getConfiguration(), KEYSPACE, COLUMN_FAMILY);
		SlicePredicate predicate = new SlicePredicate().setColumn_names(Arrays.asList(columnName.getBytes()));
		ConfigHelper.setSlicePredicate(job.getConfiguration(), predicate);

		boolean status = job.waitForCompletion(true);
		System.exit(status ? 0 : 1);
	}
}
輸出的結果為:
forecasts	1
home	4
in	3
increase	1
july	3
new	2
rise	2
sales	4
top	1
2010-08-09 15:27:32 | Add Comment